

Quick Summary
- Blind LLM agents lack context, increasing susceptibility to adversarial manipulation and data leakage.
- Security flaws stem from blind agents' autonomous decision-making without environment feedback.
- Recent attacks exploit blind LLMs via prompt injection and API abuse, raising operational risks.
- Mitigation involves layered defenses: input sanitization, behavioral monitoring, and model explainability.
- Industry adoption faces hurdles due to trust deficits and high costs of securing blind LLM deployments.
Blind LLM agents represent a growing security concern as they autonomously execute tasks without direct access to user feedback or environmental context. This architectural choice, while enabling automation, exposes critical vulnerabilities that attackers increasingly exploit in 2026.
These agents operate in a trade-off space between autonomy and security, complicating defenses. As enterprises deploy blind LLM agents for complex workflows, understanding their unique attack surfaces is essential to avoid costly breaches and operational disruptions.
Why Blind LLM Agents Amplify AI Security Vulnerabilities
Blind LLM agents are AI systems that process inputs and produce outputs without continuous feedback or environmental awareness. This lack of real-time context makes them inherently vulnerable to manipulation, such as prompt injections and adversarial inputs that can alter their behavior unexpectedly.
Unlike interactive AI models, blind agents must rely solely on their training data and initial prompts, which attackers can exploit by crafting malicious inputs designed to bypass safeguards. This elevates the risk of data leakage, unauthorized actions, or misinformation propagation.
Recent security incidents highlight how blind LLM agents exposed sensitive information by misinterpreting ambiguous instructions or executing harmful commands. These failures underline the need for tighter control mechanisms and robust input validation within blind agent architectures.
Organizations must weigh the operational gains of blind LLM agents against these amplified risks. For a deeper understanding of AI security frameworks, see our analysis on AI in Cybersecurity: Enhancing Threat Detection in 2026.
How Prompt Injection Attacks Exploit Blind LLM Agents’ Autonomy
Prompt injection is a primary attack vector against blind LLM agents, where adversaries insert malicious instructions into input prompts to manipulate the agent's output or behavior. Since blind agents lack environment feedback, they cannot verify or reject these injections effectively.
What makes blind LLM agents especially vulnerable to prompt injections?
Blind LLM agents process inputs in isolation, without cross-checking external context or user intent, allowing injected prompts to hijack their logic flow. This can result in unauthorized data access, altered task execution, or propagation of harmful content.
Security researchers have documented attacks where blind agents inadvertently reveal confidential data or perform unintended operations due to subtle prompt manipulations. These exploits bypass traditional input sanitization, demanding new defensive paradigms.
Mitigation strategies include strict input validation, multi-step confirmation protocols, and integrating explainable AI modules that flag anomalous reasoning paths. For a broader perspective on defense technologies, visit our feature on AI Defence Technologies Emerge as Top Priority in International Security.
The Trade-Off Between Autonomy and Security in Blind LLM Deployments
Blind LLM agents provide automation benefits by reducing human intervention, but this autonomy introduces security trade-offs. Without feedback loops, these agents can’t adapt or correct mistakes dynamically, increasing the risk of persistent vulnerabilities.
Deploying blind LLM agents in critical environments demands balancing efficiency gains with potential attack surfaces. Over-restricting inputs may reduce utility, while lax controls invite exploitation.
How can organizations balance these competing demands?
Layered defense-in-depth architectures combining behavioral monitoring, anomaly detection, and human-in-the-loop oversight are currently the best practice. However, these add complexity and operational costs, limiting scalability.
Enterprises must also consider the maturity of their AI governance frameworks and compliance requirements. Blind LLM agents without robust audit trails or explainability exacerbate regulatory risks.
Our coverage on Explainable AI in Cybersecurity: Boosting Threat Detection provides insights into improving transparency and trust in autonomous AI systems.
Real-World Examples of Blind LLM Agent Security Breaches in 2026
Several documented incidents in 2026 illustrate the dangers of blind LLM agents. One case involved a financial institution’s chatbot leaking sensitive client data after a crafted prompt injection attack bypassed filters.
Another example saw a blind LLM agent in an enterprise automation pipeline execute unauthorized commands due to ambiguous instructions, causing operational downtime and data integrity issues.
These breaches highlight that blind LLM agents can be a weak link in AI security chains, especially when deployed without comprehensive safeguards and monitoring.
Industry responses have included accelerated patch cycles, mandatory security audits, and collaboration efforts such as the Nvidia Open Secure AI Alliance launched to standardize protections around AI agent frameworks.
Emerging Defensive Techniques Tailored for Blind LLM Agents
To counter blind LLM agents’ security gaps, researchers and vendors are developing tailored defenses. Input sanitization frameworks now incorporate semantic analysis to detect hidden prompt injections beyond simple keyword filtering.
Behavioral anomaly detection uses model output patterns to flag deviations that may indicate tampering. This requires training on normal agent behavior to reduce false positives.
Explainability tools provide transparency into the agent’s decision process, helping security teams understand and intervene in suspicious cases.
Despite these advances, blind LLM agents still lack standardized security certifications, complicating enterprise adoption. For technical details on AI security advances, consult the Wikipedia page on Artificial Intelligence Security.
Why Blind LLM Agents Remain a Tough Security Challenge for Enterprises
Enterprises face significant hurdles securing blind LLM agents due to their opaque decision-making and limited observability. The lack of real-time feedback hampers rapid threat detection and response.
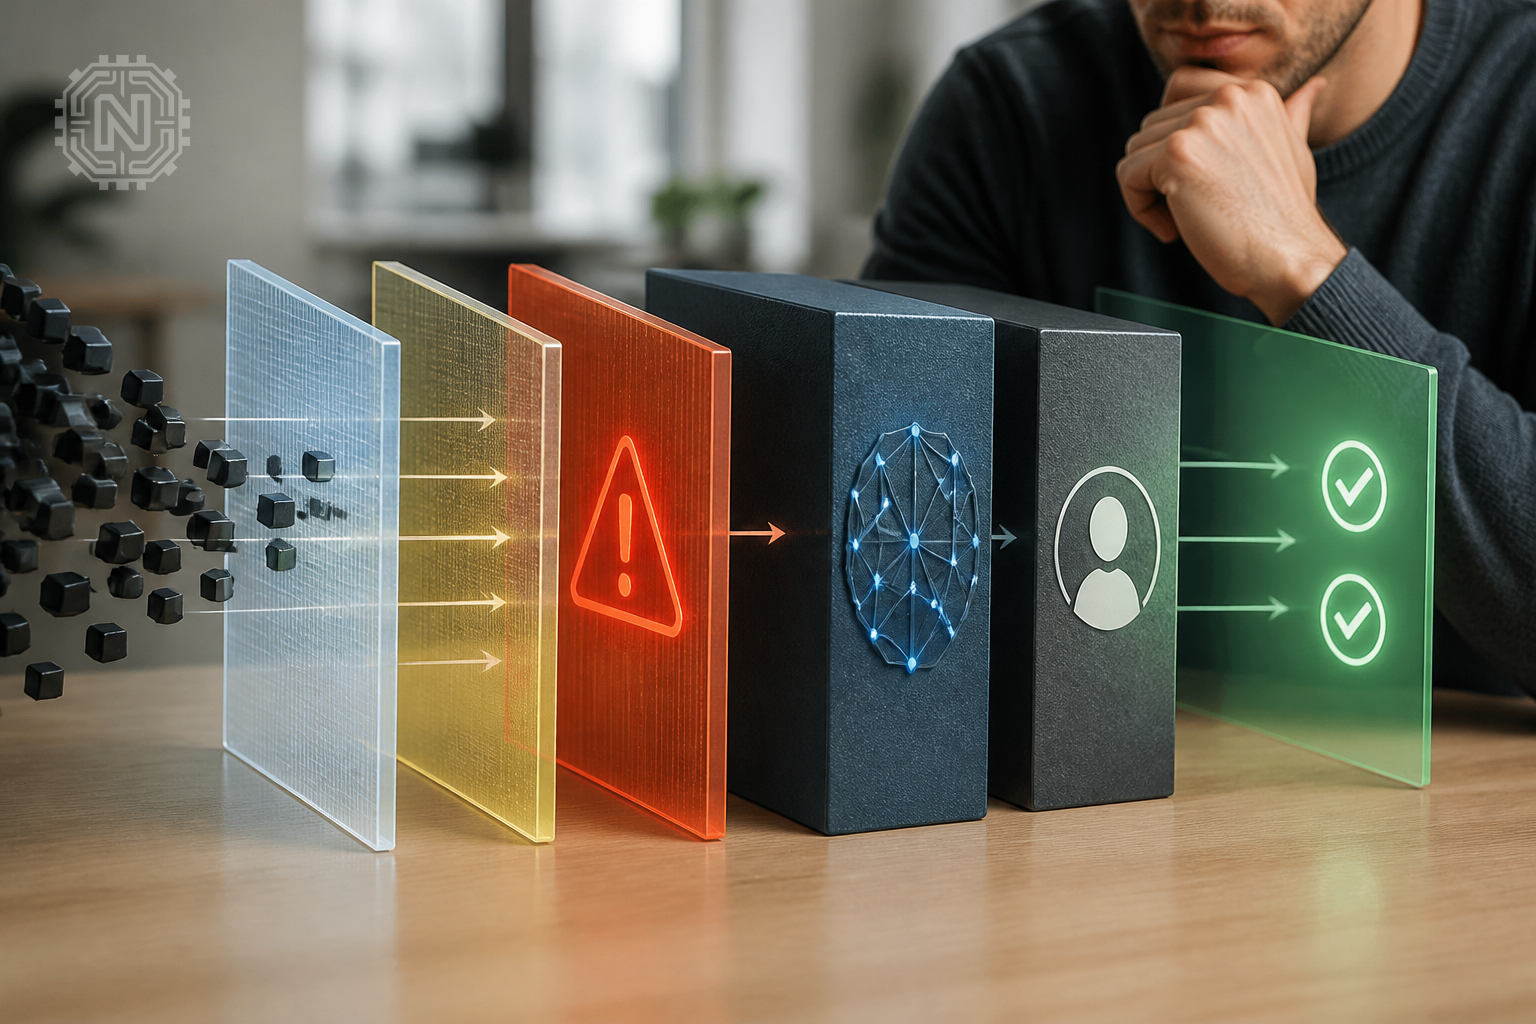
Costs for implementing multi-layered security measures and ongoing monitoring are high, often delaying deployment or forcing reliance on less autonomous AI models.
Are blind LLM agents suitable for all organizations?
Organizations with stringent compliance needs or high-security risk profiles should be cautious. Blind LLM agents may be better suited for controlled environments with human oversight.
Adoption will likely increase as security tooling matures, but for now, blind LLM agents represent a calculated risk requiring informed, proactive management.
How Regulatory and Industry Standards Are Shaping Blind LLM Agent Security
Regulators worldwide are scrutinizing AI systems, including blind LLM agents, for security and privacy compliance. Standards bodies are drafting guidelines that require transparency, auditability, and risk assessments for autonomous AI.
Industry coalitions push for shared threat intelligence and best practices, aiming to raise the security baseline across vendors and users.
These efforts will force blind LLM agent developers to embed security by design and provide clearer accountability mechanisms.
For ongoing regulatory updates, refer to OpenAI’s security research page.
Editorial Sources
The Bottom Line for Blind LLM Agent Security
Blind LLM agents offer automation advantages but introduce significant, inherent security risks due to their lack of feedback and context. Organizations must invest in layered defenses, continuous monitoring, and governance to mitigate these vulnerabilities. Until security tooling and standards mature, blind LLM agents remain best deployed with caution and human oversight.
Frequently Asked Questions
What is a blind LLM agent in AI?
A blind LLM agent is an AI model that operates without real-time feedback or environmental context, relying solely on input prompts.
Why are blind LLM agents considered less secure?
Their lack of feedback loops makes them vulnerable to prompt injections and adversarial inputs that can manipulate behavior.
Can blind LLM agents leak sensitive data?
Yes, crafted inputs can trick blind LLM agents into revealing confidential information unintentionally.
How do prompt injection attacks work against blind LLM agents?
Attackers embed malicious instructions in prompts to alter the agent’s outputs or cause unauthorized actions.
What defenses exist for blind LLM agent security?
Defenses include input sanitization, behavioral anomaly detection, explainability tools, and human oversight layers.
Are blind LLM agents suitable for all industries?
No, industries with strict security or compliance needs should approach blind LLM agents cautiously due to inherent risks.
What role do regulations play in blind LLM agent security?
Regulations push for transparency, auditability, and risk assessments to ensure safer deployment of autonomous AI systems.
How can organizations monitor blind LLM agents effectively?
By implementing continuous behavioral monitoring and anomaly detection systems tailored to blind agent outputs.
Related Topics


